MCGG Advanced Server Dataset
Overview
A fully automated OCR and data engineering pipeline designed to extract, structure, and publish game data for Magic Chess: Go Go. Built to overcome the lack of official APIs, providing the community with a structured dataset for meta-analysis.
The Challenge
Moonton does not provide a public API for Magic Chess: Go Go (MCGG). Analyzing the meta, hero stats, and synergy effectiveness requires structured data. The engineering challenge: Extracting thousands of data points ethically, without reverse-engineering game binaries or violating Terms of Service.
The Engineering Approach
I developed a custom AI-powered vision pipeline utilizing Gemini 2.5 Flash to extract data directly from the game’s visual layer. The core extraction engine handles screenshot ingestion, context merging, and JSON structuring:
# --- THE DEEP SCANNER V3.5 (Core Extraction Engine) ---
def scan_and_merge(image, hero_map, existing_data=None):
    if existing_data:
        context_instruction = f"""
        MODE: UPDATE & MERGE.
        DATA EXISTING: {json.dumps(existing_data)}
        TUGAS:
        1. Gabungkan deskripsi skill yang terpotong di data existing dengan teks di gambar baru.
        2. Lengkapi base_stats yang masih 0.
        3. PERTAHANKAN data yang sudah lengkap/benar.
        """
    else:
        context_instruction = "MODE: NEW ENTRY. Ekstrak data dari nol."

    prompt = f"""
    {context_instruction}
    Analisis Detail Hero Magic Chess. Tabel Atribut (Kanan Atas) & Atribut Skill (Kanan Bawah).

    OUTPUT JSON TARGET:
    {{
      "hero_name": "Nama Hero",
      "cost": 5,
      "base_stats": {{
        "hp": [v1, v2, v3],
        "physical_atk": [v1, v2, v3]
        # ... other stats
      }},
      "skill": {{
        "name": "Nama Skill",
        "description": "Deskripsi FULL (Sambung kalimat terpotong)."
      }}
    }}
    """

    try:
        # Utilize Gemini 2.5 Flash Vision for blazing fast OCR & Structuring
        response = client.models.generate_content(model='gemini-2.5-flash', contents=[prompt, image])
        clean_json = response.text.replace("```json", "").replace("```", "").strip()
        data = json.loads(clean_json)

        # Inject Synergies automatically by cross-referencing DB
        clean_name = data.get('hero_name', '').strip().lower()
        if clean_name in hero_map:
            data['synergies'] = hero_map[clean_name]

        return data
    except Exception as e:
        return None
The pipeline resolves fragmented screenshots by merging incomplete OCR strings and populating missing statistics into the database.
The complete extraction pipeline targets three core domains:
- Heroes: Base stats (HP, Attack) and dynamic Skill Multipliers.
- Synergies: Trait activation thresholds and effects.
- Cards: Battle and Power card modifiers.
Sample Data Output (Hero Example)
Raw pixel data is parsed and structured into relational JSON:
{
  "hero_name": "Miya",
  "cost": 3,
  "base_stats": {
    "hp": [2170, 3906, 7378],
    "physical_atk": [130, 195, 260],
    "magic_atk": [130, 195, 260],
    "atk_speed": [0.8, 0.8, 0.8],
    "attack_range": [4, 4, 4],
    "mana_initial": [50, 50, 50],
    "mana_max": [70, 70, 70]
  },
  "skill": {
    "name": "Moon Arrow",
    "description": "Miya gets 50% ATK Speed for 5 seconds. During this duration, he fires 1 additional Split Arrow which deals 50% DMG and activates the Basic ATK Effect.",
    "skill_attributes": [
      {
        "name": "ATTACK Speed Bonus",
        "values": ["50%", "50%", "55%"]
      },
      {
        "name": "Split Arrow",
        "values": ["1", "2", "3"]
      }
    ]
  },
  "synergies": ["Heartbond", "Marksman"]
}
The Result
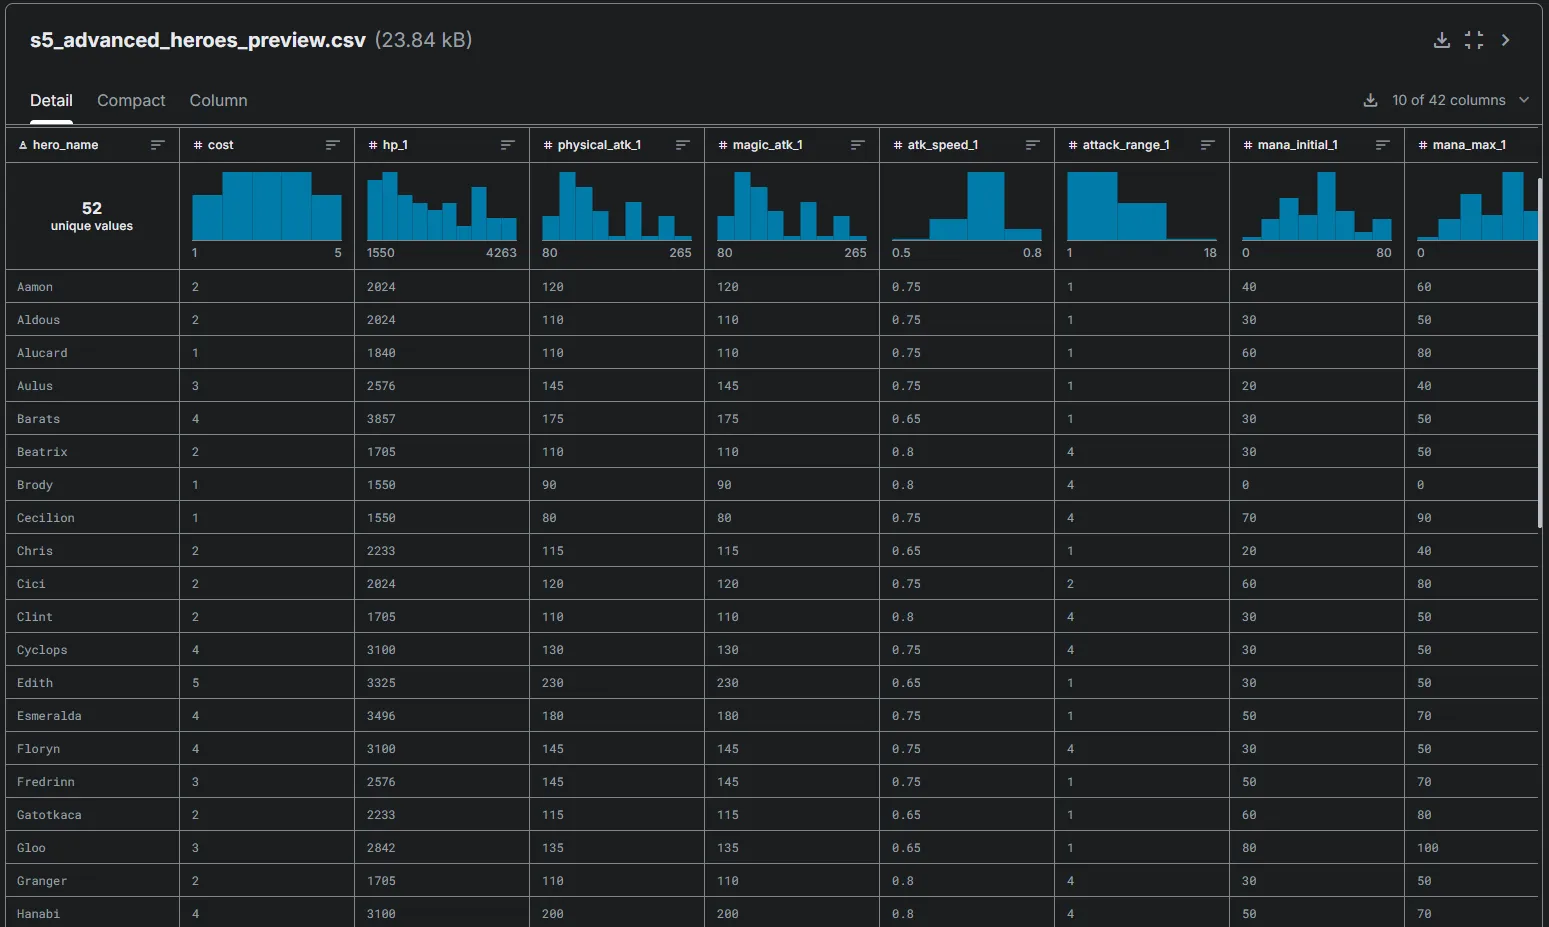
The dataset (Patches 1.2.54 - 1.2.56) is published on Kaggle, providing structured data for machine learning models and meta-analysis. The visual-only extraction method guarantees 100% compliance with Fair Use guidelines, acting purely as an open-source contribution.
You can view the raw data and community analysis on the Official Kaggle Page.